SQL MIN() and MAX() Functions Explained with Examples
For someone who writes SELECT queries and now needs the smallest or largest value in a column; GROUP BY and HAVING are explained where they appear.
On this page
A report asks for the lowest and the highest salary a table holds, and each of those numbers takes one function call. SQL MIN() returns the smallest value in a column and SQL MAX() the largest, both written with a single column name inside the brackets.
SELECT MIN(column_name)   -- the smallest value in the column
FROM table_name;

SELECT MAX(column_name)   -- the largest value in the column
FROM table_name;
- Both are aggregate functions, so one row comes back however many rows the query reads.
- Rows where the column is NULL are skipped rather than read as zero.
- A group holding no non-NULL value returns NULL, not 0[1].
- The value comes back in the type of the column it was taken from[3].
The SQL MIN() and MAX() functions
Every query on this page runs against the same three-row Employees table.
| EmployeeID | FirstName | LastName | Department | Salary | HireDate |
|---|---|---|---|---|---|
| 1 | John | Doe | IT | 50000 | 2019-03-04 |
| 2 | Jane | Smith | HR | 60000 | 2021-07-19 |
| 3 | Sam | Brown | IT | 55000 | 2020-11-02 |
Both functions sit in the SELECT list and collapse every row the query selects into one value, so a single statement returns both bounds:
SELECT MIN(Salary) AS MinSalary,
       MAX(Salary) AS MaxSalary
FROM Employees;
| MinSalary | MaxSalary |
|---|---|
| 50000 | 60000 |
50000 is John Doe's salary and 60000 is Jane Smith's, and the result says nothing about which employee earns either one. Without the aliases the two headers would come back as MIN(Salary) and MAX(Salary). Neither function accepts more than one column, so comparing two columns of the same row takes a row-level function such as GREATEST or LEAST[3] rather than an aggregate.
Rows where Salary is NULL are skipped rather than read as zero, and both functions return NULL themselves only when the group they run over holds no non-NULL value at all, which is the documented behaviour in SQLite[1], in MySQL[2] and in SQL Server[3] alike.
An empty result behaves the same way. Apart from COUNT, PostgreSQL aggregate functions return NULL rather than zero when no rows are selected[6], so wrap the call in COALESCE where the code downstream expects a number.

Selecting the full row that holds the MIN or MAX value
Knowing that the highest salary is 60000 is rarely the end of the question. The usual follow-up is which employee earns it, and that needs the whole row. The portable pattern is a subquery in the WHERE clause: compute the aggregate once, then select the rows that match it.
SELECT EmployeeID, FirstName, LastName, Salary
FROM Employees
WHERE Salary = (SELECT MAX(Salary) FROM Employees);
| EmployeeID | FirstName | LastName | Salary |
|---|---|---|---|
| 2 | Jane | Smith | 60000 |
Swapping MAX for MIN returns John Doe on 50000 instead. Ties return every matching row, so two employees on 60000 both come back. And the subquery is evaluated over the whole table unless you repeat the outer filter inside it, so a WHERE Department = 'IT' outside still compares against the company-wide maximum.
For the highest-paid employee per department, the same subquery has to be correlated:
SELECT EmployeeID, FirstName, LastName, Department, Salary
FROM Employees e
WHERE Salary = (SELECT MAX(Salary)
                FROM Employees
                WHERE Department = e.Department);
Two engine-specific shortcuts do the same job with less typing. PostgreSQL offers DISTINCT ON[4], which keeps the first row of each group after an ORDER BY, and SQL Server exposes MIN and MAX as window functions through an OVER clause[3], which computes the aggregate per partition while keeping the individual rows intact.
MIN() and MAX() with GROUP BY and ORDER BY
Without GROUP BY, MIN() and MAX() reduce the entire table to one row. Adding a GROUP BY clause changes the unit of aggregation: the engine forms one group per distinct value of the grouping column and returns one minimum and one maximum per group. ORDER BY then sorts those groups by the aggregate that was just computed, which is how the highest-paying department reaches the top.
SELECT Department,
       MIN(Salary) AS MinSalary,
       MAX(Salary) AS MaxSalary
FROM Employees
GROUP BY Department
ORDER BY MaxSalary DESC;
The Employees table holds two departments, so the result holds two rows:
| Department | MinSalary | MaxSalary |
|---|---|---|
| HR | 60000 | 60000 |
| IT | 50000 | 55000 |
HR contains only Jane Smith, so its minimum and maximum are the same number. IT contains John Doe on 50000 and Sam Brown on 55000, so the two differ, and DESC puts HR on top. The alias is safe in this clause: PostgreSQL allows a query output column to be referenced by name or by ordinal number[4] in GROUP BY and in ORDER BY, so ORDER BY MaxSalary and ORDER BY MAX(Salary) mean the same thing. The HAVING clause is where that stops being true.
Grouping also governs which other columns you are allowed to select. A query such as SELECT FirstName, MIN(Salary) FROM Employees is rejected by PostgreSQL and by SQL Server, because FirstName is neither grouped nor aggregated and the engine has no way to decide which of the three names to print. MySQL rejects it too when ONLY_FULL_GROUP_BY[5] is enabled, and MySQL enables it by default. Every column in the SELECT list therefore has to be either inside an aggregate or named in the GROUP BY.
WHERE and HAVING with MIN() and MAX()
The two clauses run at different points in the query. WHERE filters individual rows before grouping happens, so an aggregate cannot appear in it: at that moment the groups do not exist yet. HAVING filters the grouped rows[4] after the aggregates have been computed, which is where a condition on MIN() or MAX() belongs.
This query is rejected by every engine, because MAX() is evaluated after WHERE:
SELECT Department, Salary
FROM Employees
WHERE Salary = MAX(Salary);
There are two correct rewrites, and they answer different questions. To filter rows against an aggregate of the whole table, put the aggregate in a subquery, which WHERE evaluates as an ordinary scalar value. To filter whole groups against their own aggregate, use the HAVING clause instead:
SELECT Department, MAX(Salary) AS MaxSalary
FROM Employees
GROUP BY Department
HAVING MAX(Salary) > 55000;
| Department | MaxSalary |
|---|---|
| HR | 60000 |
Only HR clears the threshold, so IT drops out of the result entirely rather than coming back with a filtered-down maximum. That is the difference HAVING makes: it removes groups, it does not adjust them.
Note that the condition repeats MAX(Salary) rather than reusing the MaxSalary alias. Repeating the aggregate is the portable form, because PostgreSQL requires every column referenced in a HAVING condition to be a grouping column or to sit inside an aggregate[4], so the alias fails there. MySQL accepts the alias, and its own manual calls that an extension to standard SQL[5].
MIN() and MAX() on text and date columns
MIN() and MAX() are not restricted to numbers. Any type with a defined sort order works, and SQL Server names the exception explicitly: MAX works on numeric, char, nchar, varchar, nvarchar, uniqueidentifier and datetime columns, but not on bit columns[3].
SELECT MIN(FirstName) AS FirstName_Low,
       MAX(FirstName) AS FirstName_High,
       MIN(HireDate)  AS EarliestHire,
       MAX(HireDate)  AS LatestHire
FROM Employees;
| FirstName_Low | FirstName_High | EarliestHire | LatestHire |
|---|---|---|---|
| Jane | Sam | 2019-03-04 | 2021-07-19 |
On a date column MIN() is the oldest date and MAX() the newest, so the earliest hire is John Doe in March 2019 and the latest is Jane Smith in July 2021.
On the text column the reading needs a caveat. Jane and Sam come back because of the column's collation rather than alphabetical order in the everyday sense. SQL Server puts it exactly: for character columns MAX finds the highest value in the collating sequence[3]. Where that sequence is a byte order rather than a language order the answer changes, because the ASCII uppercase letters all sort before the lowercase ones. PostgreSQL's C and POSIX collations sort by byte values rather than natural language order[7], so a column collated C returns 'Zoe' as the minimum and 'adam' as the maximum, while the same two rows under a linguistic collation such as en_US return 'adam' and 'Zoe'.
If the result has to be alphabetical regardless of case, normalise inside the function: MIN(LOWER(FirstName)) sorts on the lowercased value, at the cost of returning the lowercased string rather than the stored one.
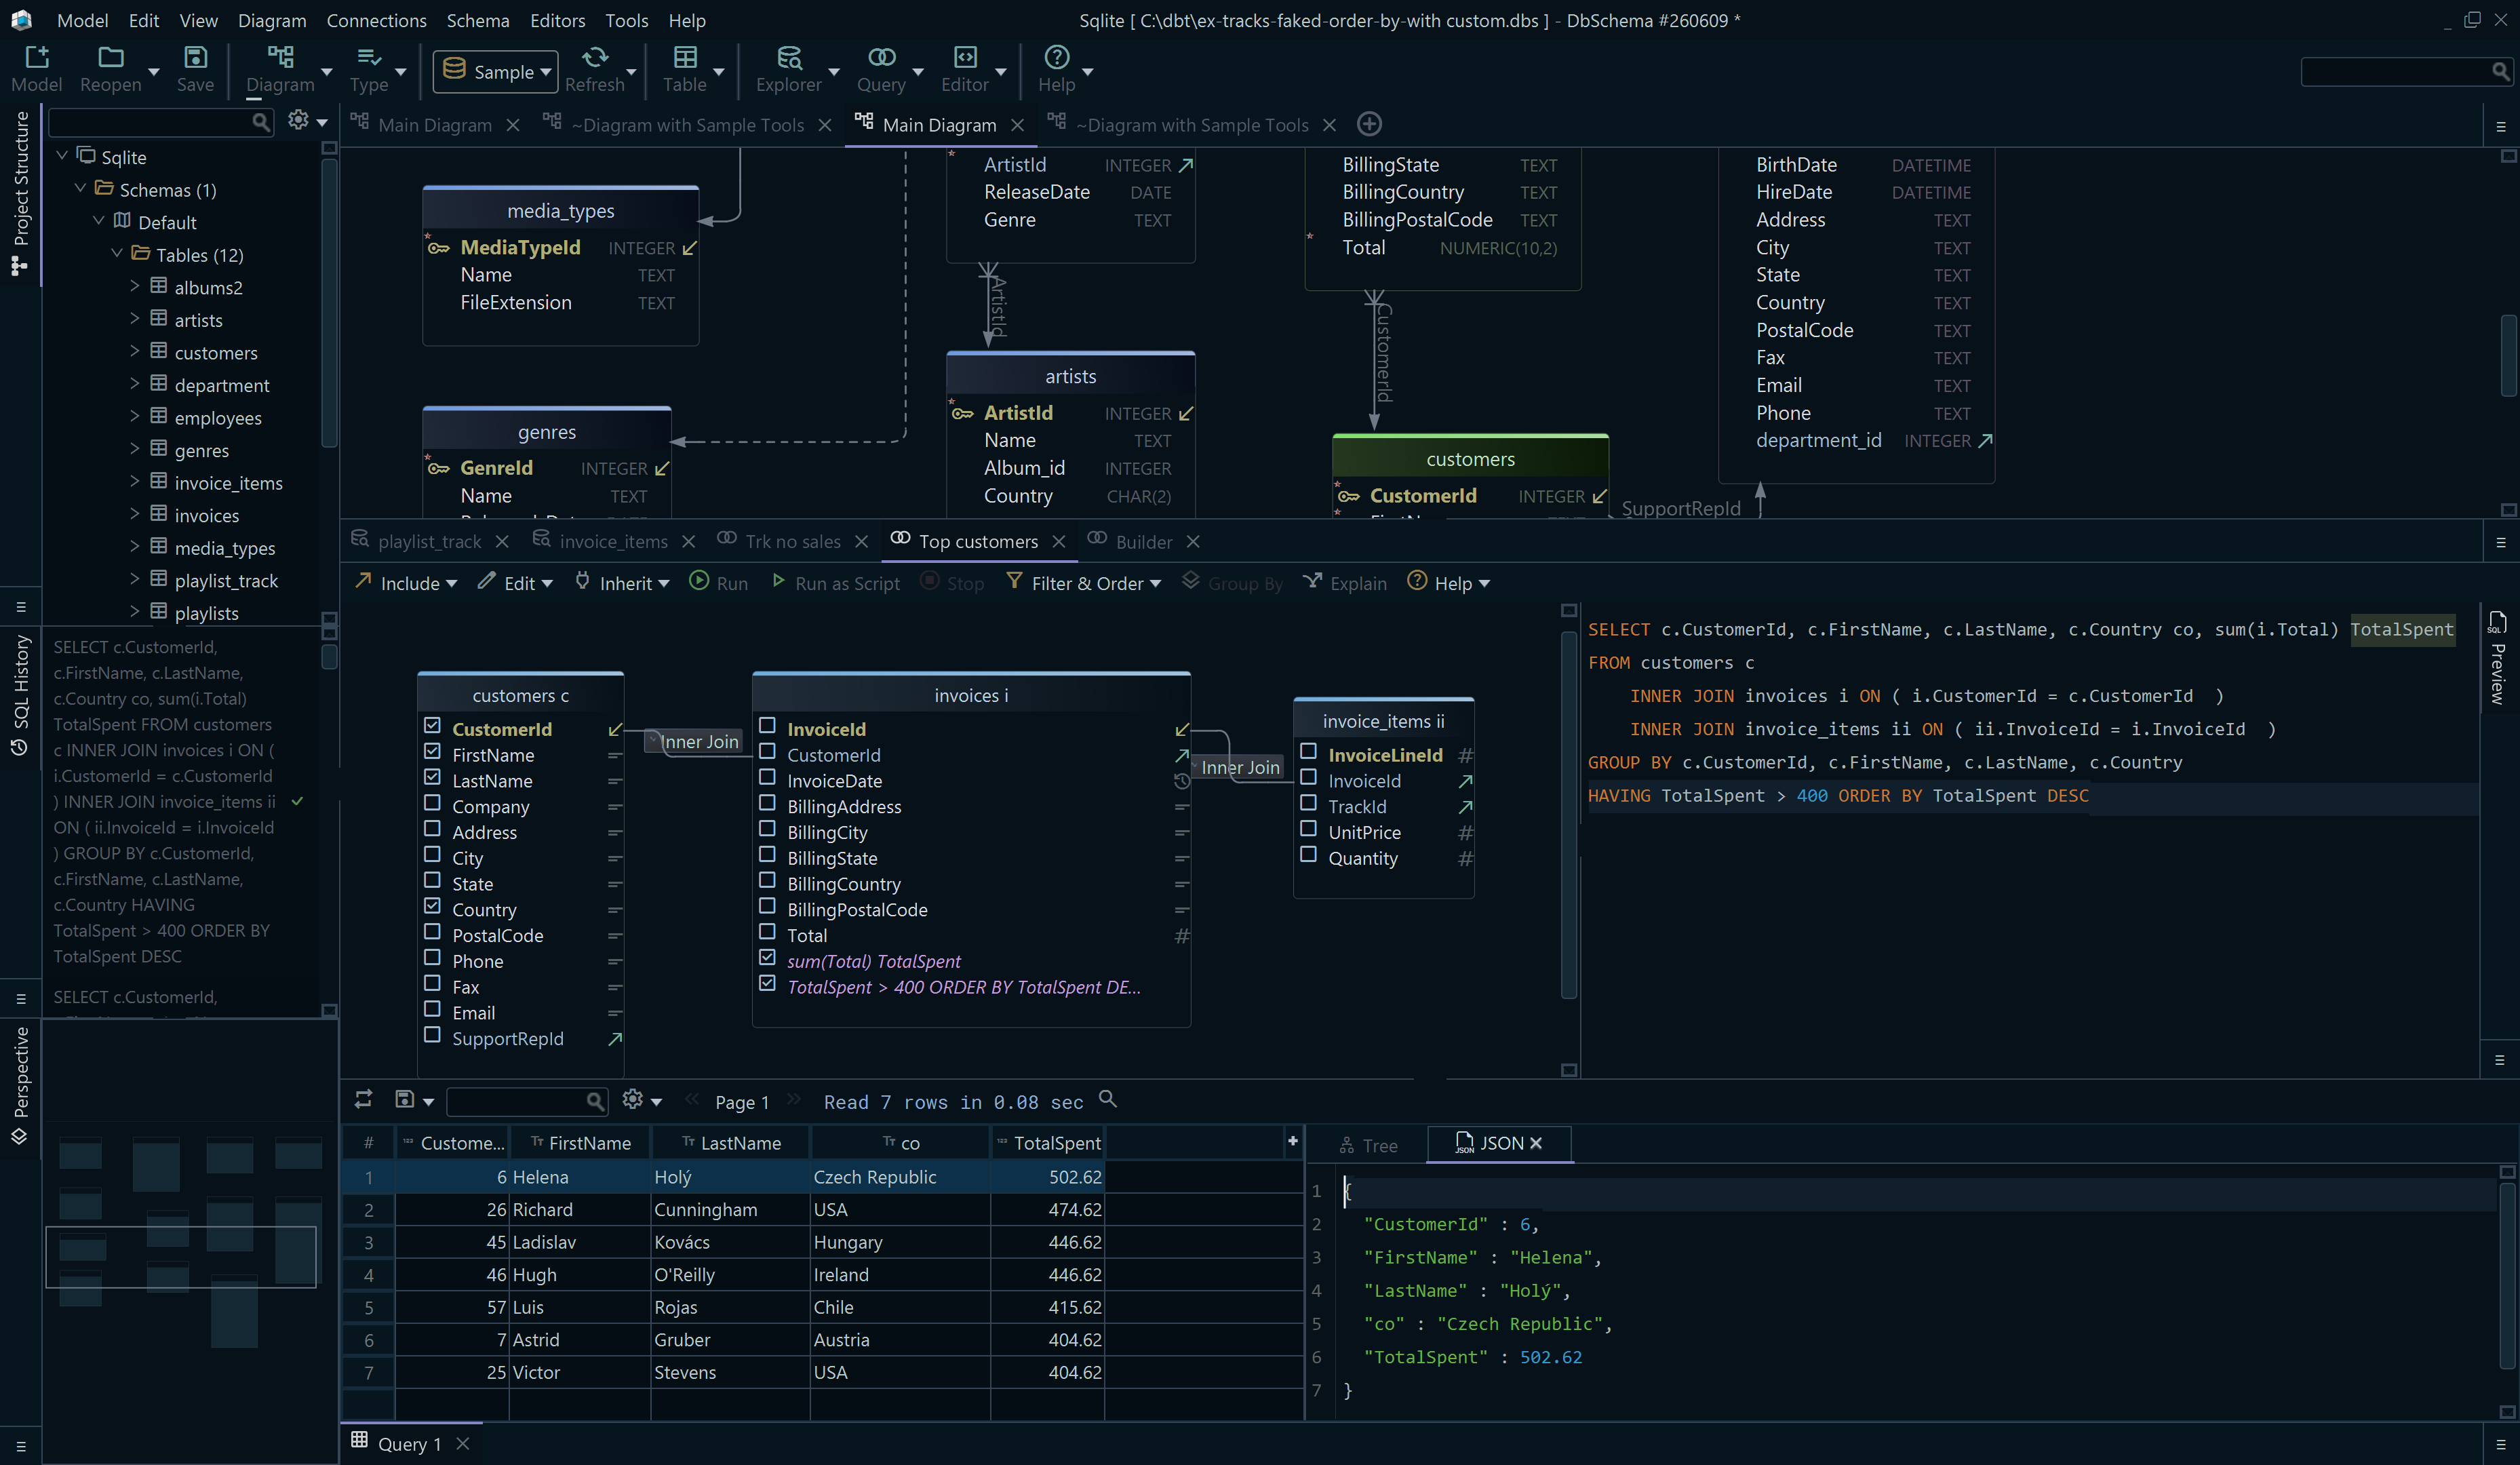
Checking MIN() and MAX() results in DbSchema
Most MIN() and MAX() mistakes are silent: the query runs and returns a number that looks exactly like the right one. DbSchema puts the statement and the rows it produced on one screen.
- Open the SQL Editor from the Editors menu.
- Paste the aggregate query and click Execute Query, which runs it against the connected database.
- Read the row in the result table, then open the SQL History pane, which records every statement executed in the session.
The history is how you confirm the aggregate came from the rows you expected rather than from a filter that quietly removed some. The SQL Editor runs against the live database, and DbSchema saves the editor itself in the design model file, so the query is still there next time you open the model.
To assemble a grouped query without typing it, open the Query Builder, which is part of DbSchema Pro, and turn on Group By in its toolbar. Ticked columns without an aggregate become the GROUP BY columns, and right-clicking a column offers Aggregate with MIN, MAX, SUM, AVG and COUNT. The generated SQL updates as you tick and stays visible, ready to copy into application code.
Common mistakes with MIN() and MAX()
Most of the errors above have one shape. The aggregate is computed at a different moment than you assumed, and the query still returns a number.
- Putting MIN() or MAX() in WHERE instead of HAVING or a subquery.
- Reusing the SELECT alias in a HAVING condition, which PostgreSQL rejects.
- Selecting a column that is neither aggregated nor named in the GROUP BY.
- Treating a NULL result as zero, and then propagating it through arithmetic.
- Reading MAX() on a text column as alphabetical order, when the column's collation is what decides it.
MIN() and MAX() are the two simplest aggregates in SQL and the two that quietly go wrong most often, because a wrong grouping, a NULL column or an alias in the wrong clause all still return a number. Download DbSchema at https://dbschema.com/download.html, connect to your database, and run these queries in the SQL Editor, which is in the free Community Edition with the diagrams. The Query Builder that assembles a grouped query without typing it is part of DbSchema Pro.
Sources
- SQLite: Built-in Aggregate Functions
- MySQL 8.4 Reference Manual: Aggregate Function Descriptions
- MAX (Transact-SQL) - SQL Server
- PostgreSQL Documentation: SELECT
- MySQL 8.4 Reference Manual: MySQL Handling of GROUP BY
- PostgreSQL Documentation: Aggregate Functions
- PostgreSQL Documentation: Collation Support
Run your MIN() and MAX() queries against the real schema
DbSchema connects to your database, runs SQL beside the result grid, and draws the tables you are aggregating as an interactive diagram. The SQL editor and the diagrams are in the free Community Edition.









