ERD Diagrams | MySQL Database Design and Docs with DbSchema
For a developer or DBA who runs a MySQL database and wants to design, document and browse it visually; every menu path is the one DbSchema shows.
On this page
Your MySQL schema has grown past the point where you can hold it in your head, and the only description of it is the DDL. DbSchema connects to the server, reverse-engineers every table and foreign key into a diagram, and keeps that structure in a design model file you can edit offline, document, put in Git, and compare against the live database later.
Connect to MySQL and reverse-engineer the schema
Click Connect to Database and pick MySQL from the list of database types. DbSchema downloads the JDBC driver for it and opens the Connection Dialog already set up for MySQL, so there is no jar to find. On the Connection tab, choose This computer, default port for a server on your own machine or Remote computer or custom port to type the Server Host and Port yourself. Fill in the Database User and Password, tick Remember to keep the password locally, and click Test Connection to check the server answers before you commit to it.
Pick the database and click Connect. DbSchema reads the schema, builds the model, and draws the tables. Against a production server, tick Read Only Connection on the Settings tab first: DbSchema then opens the connection in read-only mode and MySQL refuses every change made through it. The MySQL page lists what else DbSchema reads from the engine.

Read the tables and foreign keys off the diagram
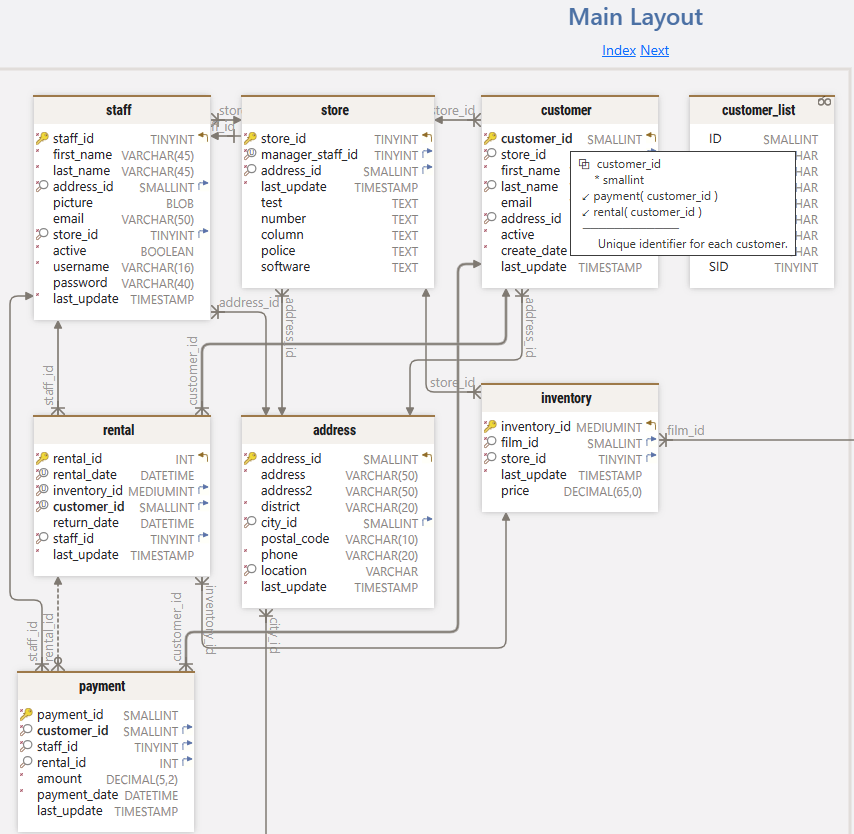
The diagram is the model, laid out. Every table is a box with its columns and primary key markers, and every foreign key is a line between two boxes whose arrow notation carries the cardinality. Open the Diagram menu and enable Show Column Types to put the data types next to the column names, or switch the notation between Default crow-foot symbols, Barker and Simple lines.
One MySQL schema usually deserves several diagrams. Add one from the Diagram menu and drag onto it only the tables of the area you are working on, so the orders view stays readable while the reporting tables sit on their own canvas. Where MySQL has no foreign key to draw, because the tables use MyISAM or the constraint was never declared, drag a column onto the related column in another table to create a virtual foreign key. It is saved in the model file and never sent to MySQL, and DbSchema treats it as a real relationship for data browsing and query building.

Export the schema as interactive HTML5 documentation
Choose Diagram → Export HTML5 or PDF Documentation and DbSchema writes the schema documentation in HTML5, PDF or Markdown. The HTML5 output opens in any browser with no server behind it: the diagram is a vector image, the table list is searchable, and clicking a table jumps to its columns, keys and indexes. Hand it to the people who need to understand the MySQL schema without an account on the server.
What makes that output worth reading is what you put in the Description field of each table and column, because those descriptions become the text of the document and the mouse-over tooltips in the HTML5 version. DbSchema also stores comment tags, key-value pairs attached to a table or a column, for metadata such as an owner or a sensitivity level. Descriptions and tags live in the model file, so they survive the next reverse-engineering.
Keep the model file in Git
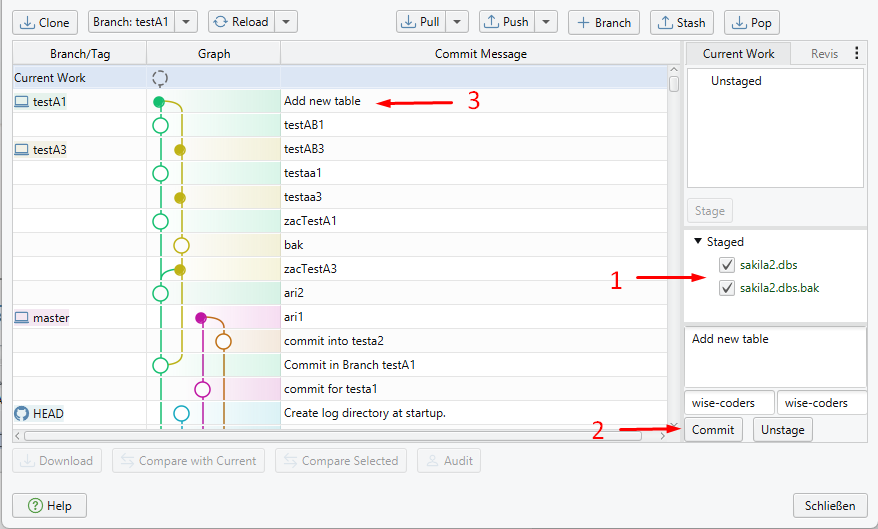
The design model is a single .dbs file in XML, which means Git can diff it like source. Open the Model menu and choose Git — Collaborative Design to reach the Git dialog, enter the remote repository URL and your credentials, and clone into an empty local folder. Stage the changed files, enter a commit message, commit, and push.
GitHub and Bitbucket both ask for authentication before they accept a push, so configure it once in the dialog and forget it. Going the other way, Pull fetches the team's commits and merges them into your local working directory.
The value of that is the review it makes possible. A teammate pulls your commit, opens the .dbs file, and uses Compare with Current to open the Synchronization Dialog and see exactly which tables and columns your commit changed, before anything reaches a MySQL server. Schema changes then travel the path code changes travel: a branch, a pull request, a merge.

Build queries with the Query Builder and the SQL Editor
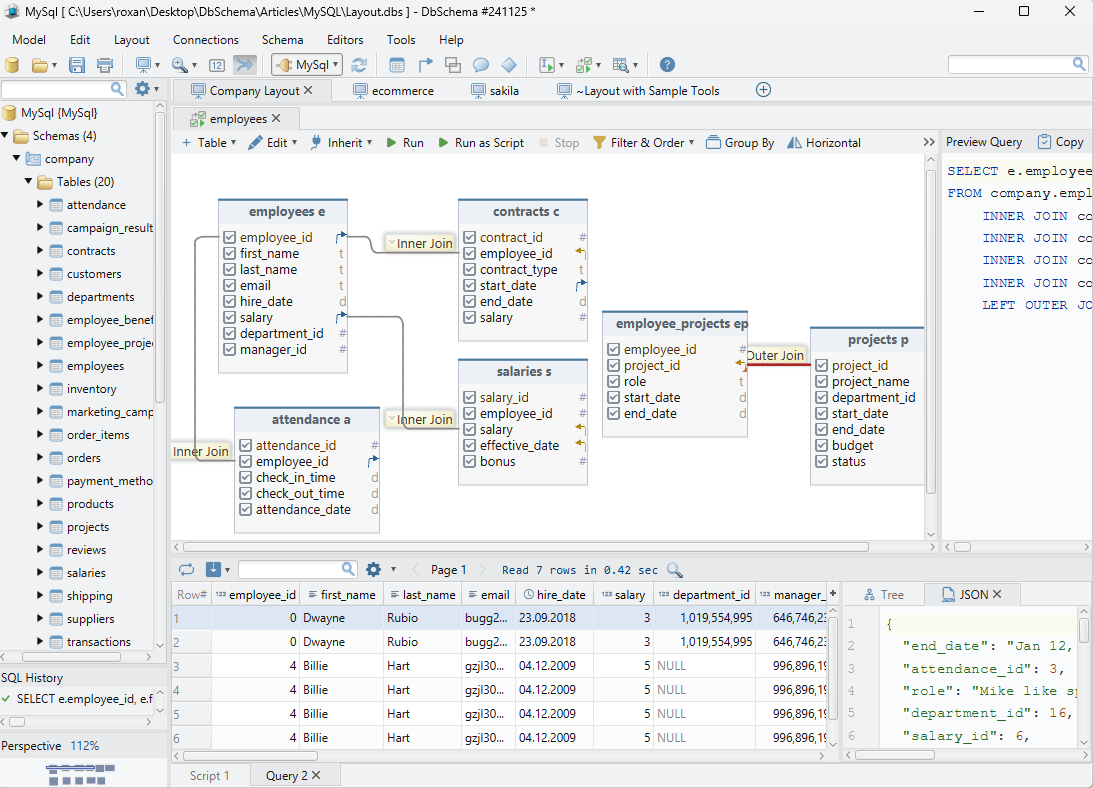
The Query Builder writes a SELECT with the mouse. Click a table header in the diagram to open it loaded with that table, then click the small arrow next to a column to follow a foreign key and pull in the related table. Click the join type label on the connecting line to switch between INNER JOIN, LEFT JOIN and EXISTS. Tick the columns you want in the SELECT list, right-click a column and choose Filter for a WHERE condition, and turn on Group By to make the ticked columns a GROUP BY and apply MIN, MAX, SUM, AVG or COUNT from the Aggregate item. The generated SQL sits at the bottom of the builder and updates as you click.
Copy that SQL into the SQL Editor when you want to take it further by hand. Ctrl+Space completes table and column names from the connected schema, Execute Query runs the statement at the cursor and shows the result as a table, and Run Script runs the whole editor. An INSERT, UPDATE or DELETE run there needs the Commit button before it is permanent, and Rollback throws it away. The builder and the editor are both stored inside the model file. Save that file with the Pro edition and a query you built in March is still there in June.
Synchronize the model with the MySQL database
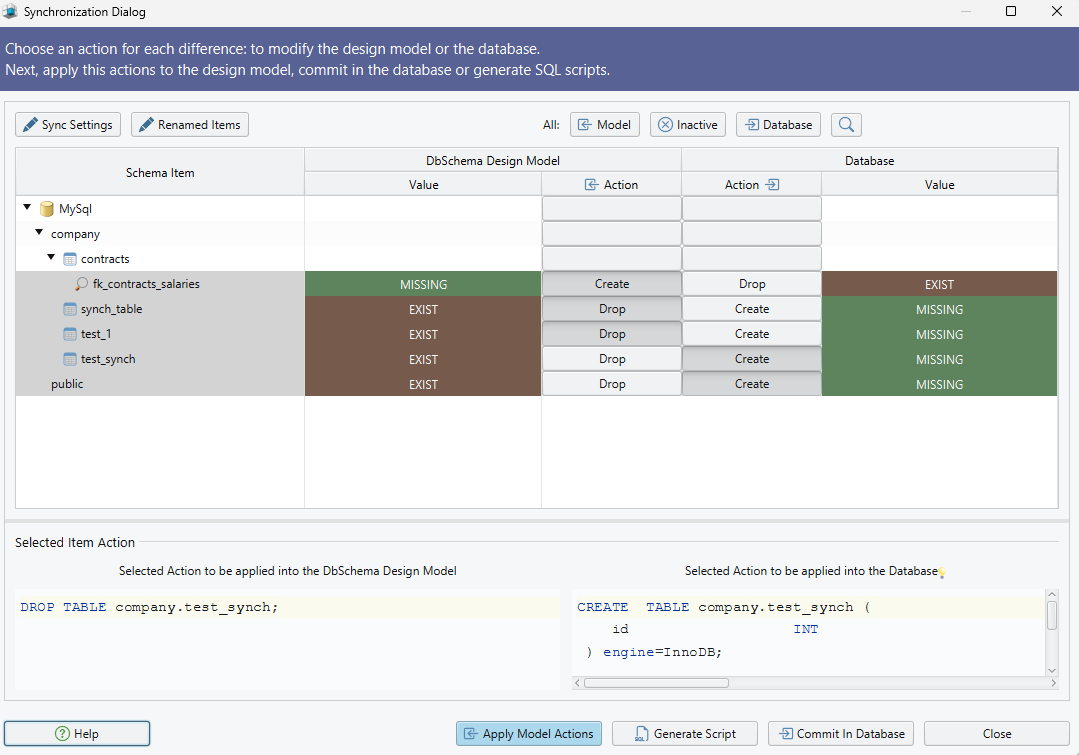
Two things drift apart: the model on your disk and the schema on the server. DbSchema reconciles them in either direction from the Schema menu. Schema → Refresh Schema from Database pulls the server's current state into the model, which is what you run after a colleague deploys a migration. Schema → Compare Model with Database lists every added, removed and modified table, column, index and foreign key, and lets you decide per object whether the model or the database is right.
Schema → Synchronize Model with Database is the one that writes. It generates the SQL that brings MySQL in line with your model, shows you those statements, lets you edit them, and runs them only when you click Execute. That distinction is the whole point of working offline: switch the connection to Disconnected and every table you add goes into the .dbs file alone, with nothing sent to MySQL until you reconnect and approve the generated script. Save the model to a file before you synchronize, so there is a previous state to go back to.
Browse related rows in the Relational Data Editor
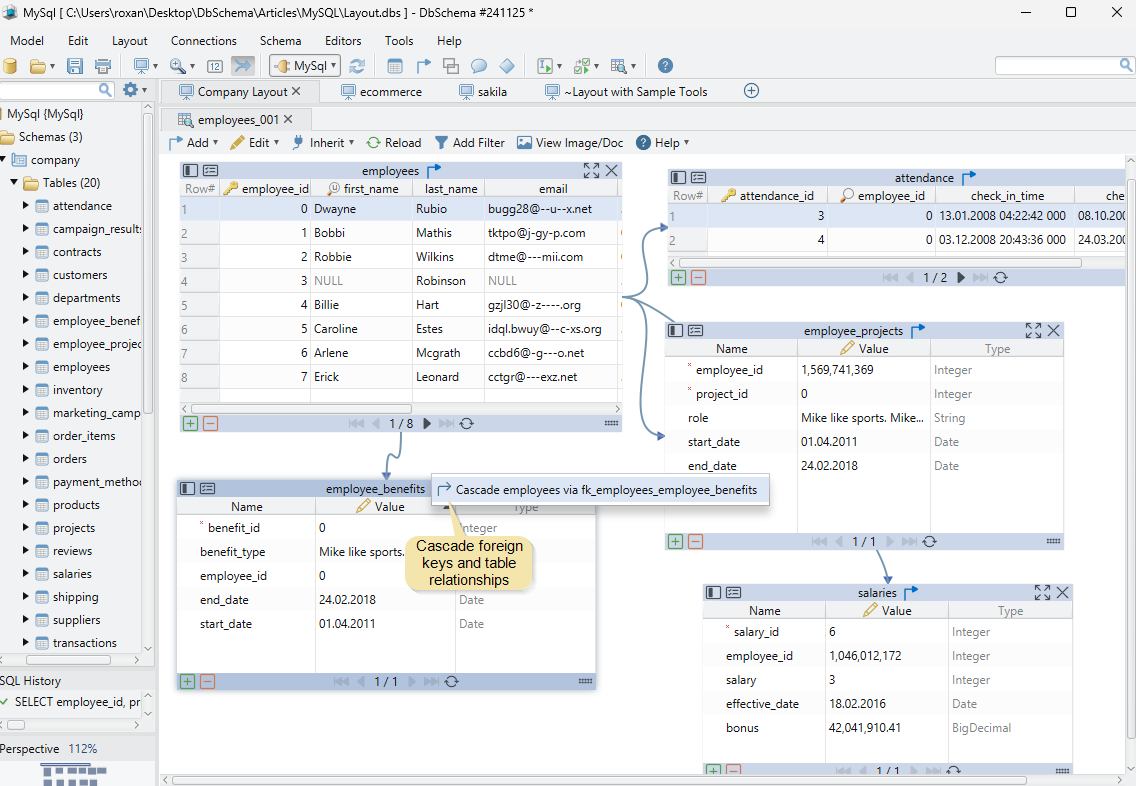
Reading one MySQL table at a time tells you little about an order. Choose New Relational Data Editor from the Editors menu, or right-click a table header and choose Open in Relational Data Editor, and the editor opens in the Tools panel at the bottom of the screen. Click the foreign key button on a table's header panel to descend into a child table, which appears as another pane filtered to the row you selected in the parent. Click a different order and every child pane refilters at once, as many levels deep as the foreign keys go.
Editing works in the same panes. The Insert button in the table footer adds a row, Edit or a double-click changes one, Delete removes one, and clicking a column header opens a filter dialog for that column. Nothing reaches MySQL until you press Commit; Rollback discards the pending changes. Where the schema has no foreign keys to follow, the virtual foreign keys you drew on the diagram serve instead.
Fill the tables with the Data Generator
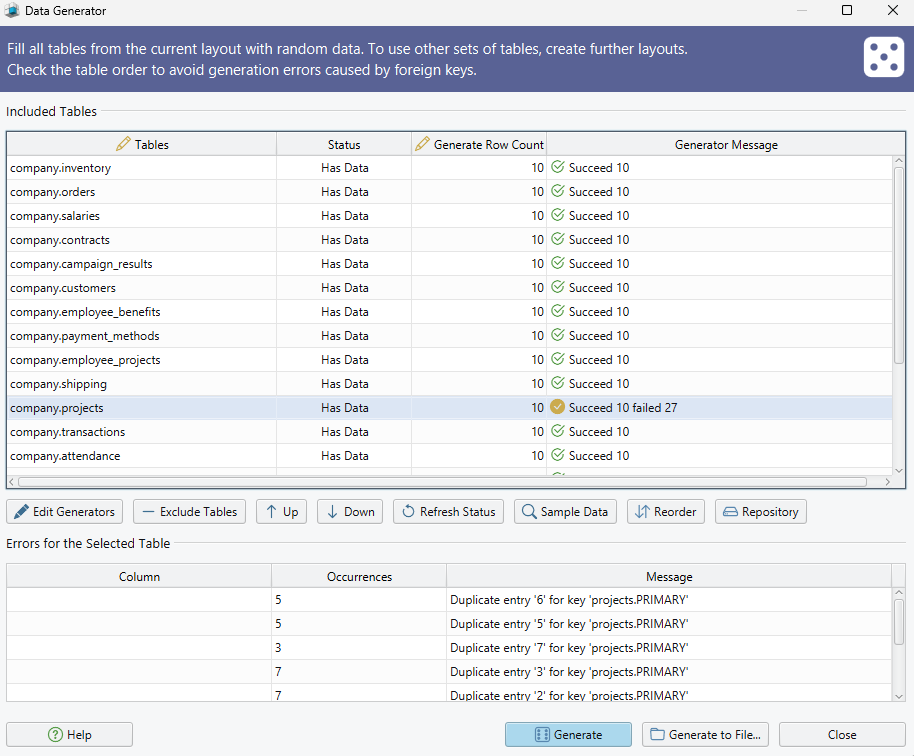
An empty schema is hard to judge, and typing rows by hand is worse. Open Data Tools → Generate Random Data to reach the Data Generator, set the number of rows per table, and let it write. Each column gets a pattern that decides how its values are made, from plain numbers and dates to reverse regular expressions and Groovy scripts, and you set the percentage of NULLs per column. Double-click a table row in the dialog to edit its patterns.
Order the tables so that a table referenced by a foreign key is populated before the table that references it, otherwise the insert fails on the constraint. The patterns are stored in the .dbs model file and reused next time; the rows themselves go into MySQL. When you click Generate, DbSchema asks whether to drop the existing data first. Do not drop data on a production database.
Every step above starts from the connection, so start there: install DbSchema from https://dbschema.com/download.html and point it at your MySQL server, and the diagram is drawn before you have written a query. Connecting, reverse-engineering, the diagrams and the SQL Editor are in the free Community Edition. Saving the model to a .dbs file, the HTML5, PDF and Markdown documentation, the Query Builder, schema synchronization, the Relational Data Editor and the Data Generator are in the Pro edition, which is also what the Git workflow above needs, since it versions that file.









