Schema Design in SQL vs NoSQL: A Visual Comparison
For the architect choosing between a relational database and MongoDB for a new application, and how the schema is designed on each.
On this page
You are planning a new application, and the shortlist has PostgreSQL on one side and MongoDB on the other. In PostgreSQL the database holds the schema and rejects any row that does not fit it. MongoDB, by default, stores any document it receives, and the schema lives in your application code.
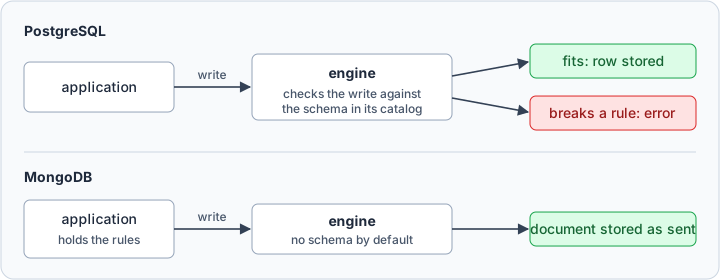
Choose PostgreSQL when several systems read the same data, such as orders joined by reports or payments that must balance. Choose MongoDB when the application reads and writes each record whole and rarely joins it. One system can use both, chosen per table or per collection.
SQL vs NoSQL schema design at a glance
A schema says what you can store, how the pieces refer to each other, and which rules the data follows. A good one keeps each fact in one place and makes the everyday queries cheap, on either kind of database. The difference is whether the database stops you when you break the rules.
SQL means the relational family. NoSQL covers the document, key-value, wide-column and graph families, such as MongoDB, Redis, Cassandra and Neo4j. Below, PostgreSQL 18 stands for the relational family and MongoDB for the document family:
| Relational (PostgreSQL) | Document (MongoDB) | |
|---|---|---|
| Schema defined | before the first row, the same for every row | by each document, unless a validation rule is set |
| Rules checked by | the engine, on every write | the application, or a validation rule |
| Relationships | foreign keys | embedded documents, or ids the application resolves |
| Joins | in the engine, across tables | none, or a $lookup stage |
| Atomic unit | any set of rows, in one transaction | one document |
| Duplication | removed by normalization | accepted where it saves a read |
| Adding a field | ALTER TABLE, a metadata change for a constant default | new documents carry it, old ones do not |
| Growing past one server | a bigger server, read-only standbys | sharding, built into the engine |
| Query language | SQL | MongoDB Query API |
Relationships and the atomic unit decide most of the design. A foreign key is a rule that PostgreSQL checks on every write. An id stored in a document is a convention that your code has to keep.
A write to one MongoDB document is atomic. Multi-document transactions exist, but MongoDB says that in most cases a multi-document transaction costs more than a single-document write, and does not replace schema design. So a MongoDB design puts data that changes together into one document. A PostgreSQL design spreads it over as many tables as the rules need.
MongoDB shards a collection across machines by a shard key, as part of the engine. A PostgreSQL database grows on a bigger server, and copies of it on standby servers answer read-only queries.
Where the schema lives in PostgreSQL
In PostgreSQL nothing can be stored until its table exists. You define the tables, columns, types and rules first, and then build the application on them. Here is the schema of a small movie review application:
CREATE TABLE users (
  user_id int PRIMARY KEY,
  name    text NOT NULL
);

CREATE TABLE movies (
  movie_id int PRIMARY KEY,
  title    text NOT NULL
);

CREATE TABLE reviews (
  review_id int PRIMARY KEY,
  user_id   int NOT NULL REFERENCES users (user_id),
  movie_id  int NOT NULL REFERENCES movies (movie_id),
  rating    int NOT NULL CHECK (rating BETWEEN 1 AND 5),
  comment   text
);

INSERT INTO users  VALUES (1, 'Ada');
INSERT INTO movies VALUES (101, 'The Third Man');
PostgreSQL rejects a review by a user who does not exist:
INSERT INTO reviews VALUES (1, 99, 101, 5, 'Enjoyed it');
ERROR:  insert or update on table "reviews" violates foreign key constraint "reviews_user_id_fkey"
DETAIL:  Key (user_id)=(99) is not present in table "users".
It also refuses to delete a user who still has reviews. The foreign key's default action is NO ACTION, which fails the delete (PostgreSQL 18 constraints):
INSERT INTO reviews VALUES (1, 1, 101, 5, 'Enjoyed it');
DELETE FROM users WHERE user_id = 1;
ERROR:  update or delete on table "users" violates foreign key constraint "reviews_user_id_fkey" on table "reviews"
DETAIL:  Key (user_id)=(1) is still referenced from table "reviews".
Settle the design before the first row goes in. Each later change to the schema runs against tables full of data, on every environment. The relational side is covered step by step in relational database schema design.
Where the schema lives in MongoDB
In MongoDB you can write data before any structure exists. The application inserts a document, and MongoDB creates the collection at that first insert (databases and collections).
Here are two reviews that PostgreSQL would reject:
db.users.insertOne({ _id: 1, name: "Ada" })
db.reviews.insertOne({ _id: 10, user_id: 99, movie_id: 101, rating: 5, comment: "Enjoyed it" })
db.reviews.insertOne({ _id: 11, userId: 1, movie: "The Third Man", stars: "5" })
MongoDB stores both reviews. User 99 does not exist, and the second review has other field names and a string for its rating.
To read a review with its author, you add a $lookup stage, MongoDB's left outer join. Here it finds no author:
db.reviews.aggregate([
  { $match: { _id: 10 } },
  { $lookup: { from: "users", localField: "user_id", foreignField: "_id", as: "author" } }
])
[
  {
    _id: 10,
    user_id: 99,
    movie_id: 101,
    rating: 5,
    comment: 'Enjoyed it',
    author: []
  }
]
Deleting a user succeeds too, and the user's reviews keep an id that points at nothing. Code that reads reviews has to handle a missing author, and a review of another shape.
Embedding, MongoDB's other option
MongoDB can also store related data inside the parent document:
db.movies.insertOne({
  _id: 101,
  title: "The Third Man",
  reviews: [
    { user_name: "Ada",   rating: 5, comment: "Enjoyed it" },
    { user_name: "Grace", rating: 4, comment: "Well written" }
  ]
})
One read returns the movie with its reviews. A write that changes both is atomic, because it touches one document. The cost is duplication: Ada's name sits in every review she wrote, and a change of name has to update every copy. A document is also limited to 16 mebibytes (MongoDB limits), so a list that grows without bound belongs in its own collection.
MongoDB's guide to embedding and references gives the criteria. By them, a movie's reviews belong in their own collection after all, because they grow without bound on a popular movie:
| Related data | Read with the parent | Written on its own | Grows without bound | Store it |
|---|---|---|---|---|
| a movie's genres | yes | no | no | embedded |
| a movie's reviews | yes | yes | yes, on a popular movie | referenced |
| a user's profile | no | yes | no | referenced |
What happens when the requirement changes
Suppose reviews need a spoiler flag. In PostgreSQL 18 that is one statement:
ALTER TABLE reviews ADD COLUMN spoiler boolean DEFAULT false;
With a constant default, PostgreSQL stores the value in the table's metadata and rewrites no rows. The ALTER TABLE documentation calls this very fast even on large tables. A volatile default, a stored generated column, an identity column or a domain type with constraints rewrites the table and its indexes. With or without a rewrite, ALTER TABLE is a migration that you review and then apply to each environment.
In MongoDB nothing has to run first. New reviews carry the field, and old ones do not:
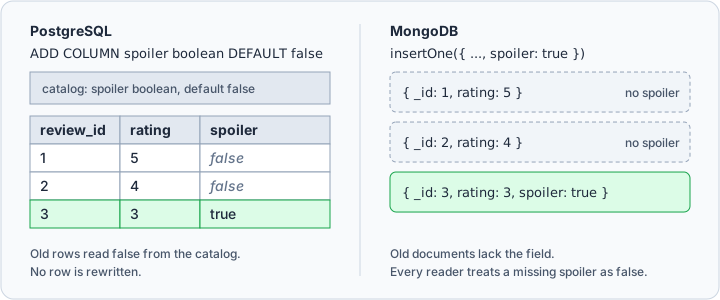
Until you backfill the old documents, every reader has to treat a missing spoiler as false. The backfill is one more statement to run:
db.reviews.updateMany({ spoiler: { $exists: false } }, { $set: { spoiler: false } })
So the migration does not disappear. It moves into the code that reads reviews, or into an update you run later.
Holding a MongoDB collection to a structure
MongoDB checks documents as they are written when the collection has a validation rule, written as a $jsonSchema:
db.reviews.drop()
db.createCollection("reviews", {
  validator: {
    $jsonSchema: {
      bsonType: "object",
      required: ["user_id", "movie_id", "rating"],
      properties: {
        rating: { bsonType: "number", minimum: 1, maximum: 5 }
      }
    }
  }
})
db.reviews.insertOne({ user_id: 1, movie_id: 101, stars: 5 })
The insert has no rating, so MongoDB rejects it with MongoServerError: Document failed validation.
The collection's validationLevel decides which writes MongoDB checks. The default, strict, checks every insert and update. With moderate, MongoDB skips the check on updates to documents that already broke the rule (validation levels). So you can add a rule to a collection that still holds documents written before the rule.
A validation rule checks one document at a time. It cannot check that user 1 exists in users, so that rule stays in the application.
The same data as a SQL diagram and a MongoDB diagram
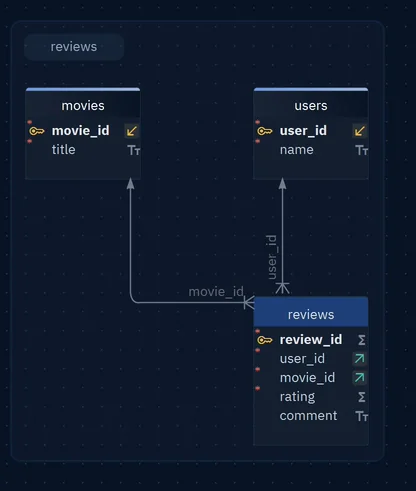
DbSchema draws both kinds of schema from the database rather than from a picture you maintain by hand. Connected to PostgreSQL, DbSchema reverse-engineers the catalog and draws the tables, the columns and the foreign keys. Here are the three tables from the schema above:
Connected to MongoDB, DbSchema reads 100 documents from the start and 100 from the end of each collection. From them it infers the field names, their types, and the nested objects and arrays. The diagram shows what those documents contain. That field list is not a schema that MongoDB enforces. Where a collection has a $jsonSchema validator, DbSchema reads the fields from the validator instead (MongoDB in DbSchema).
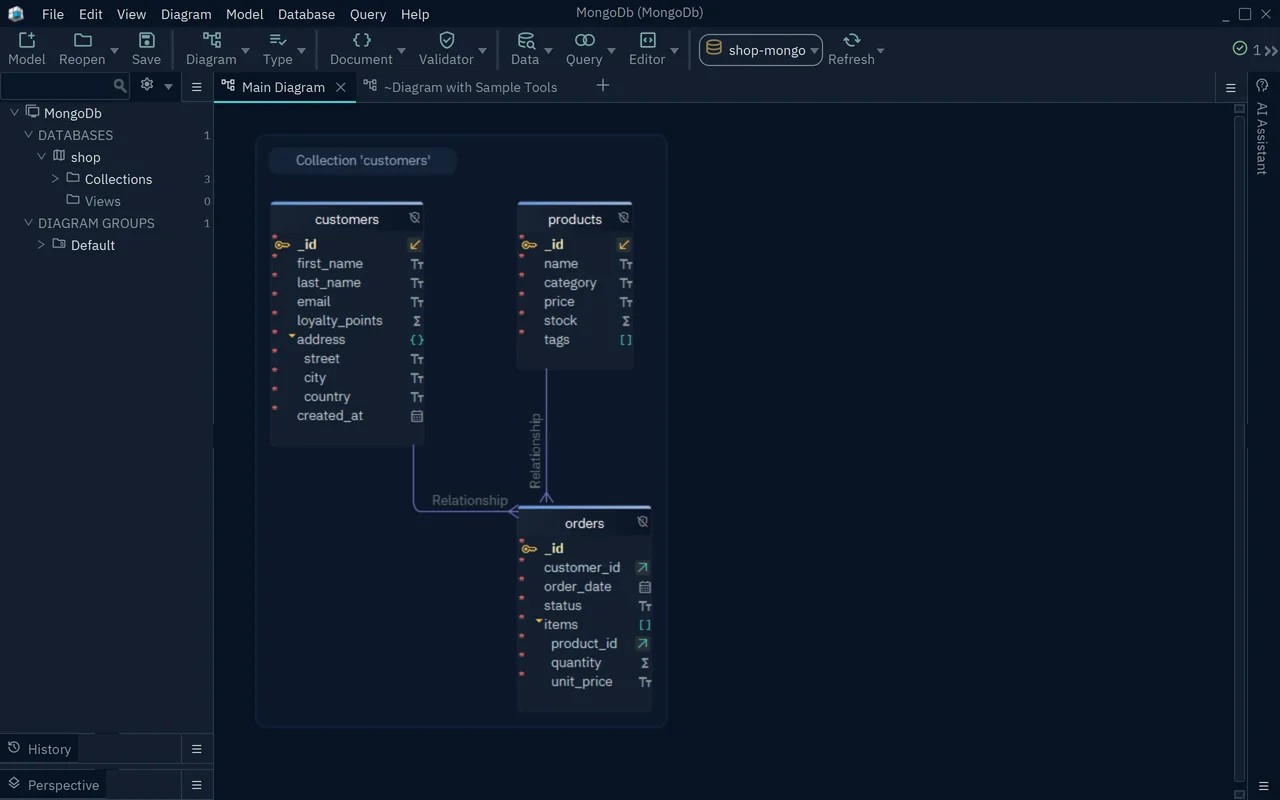
MongoDB declares no relations, so DbSchema draws a relation where a field holds the _id of a document in another collection, such as orders.customer_id in the screenshot. To add a relation that DbSchema missed, such as a review's user_id, drag the field onto the field it refers to. Such a relation is virtual: DbSchema keeps it in its model file, and MongoDB never sees it.
The Data Explorer follows the relations. Select a customer, and the pane beside it shows that customer's orders. DbSchema also exports the diagram as HTML5 documentation: a vector image of the diagram, with the comments as mouse-over tooltips. There are worked examples for MongoDB and for MySQL.
Download DbSchema, connect to the database you already have, relational or MongoDB, and reverse-engineer it into a diagram. Connecting, reverse-engineering and the diagrams are in the free Community Edition, which also documents a diagram of up to 12 tables. Saving the model file, documenting larger diagrams and the Data Explorer are in Pro.
Model SQL and MongoDB in the same diagram
DbSchema reverse-engineers relational databases and MongoDB alike, samples your documents to derive a field list per collection, and draws both as interactive ER diagrams. The Community Edition is free.









