How to Generate Random Data in PostgreSQL
For the developer who has a PostgreSQL schema in place and needs it full of believable rows before testing anything against it.
On this page
A screen built against four hand-typed rows tells you almost nothing. Pagination never triggers, and the join that will be slow comes back instantly. The first apostrophe in a surname then arrives from a real user. Random rows need two things: a value for every column that looks like what the column will hold, and a foreign key value that points at a row that exists, so the parent table has to be filled first. PostgreSQL produces both with generate_series and random(), and the DbSchema Data Generator fills PostgreSQL tables from a pattern per column. The examples ran on PostgreSQL 18.6 and use two tables:
CREATE TABLE teams (
  team_id int PRIMARY KEY,
  name    text NOT NULL
);

CREATE TABLE players (
  player_id int PRIMARY KEY,
  team_id   int NOT NULL REFERENCES teams,
  name      text NOT NULL,
  position  text
);
Generate rows with generate_series and random()
generate_series(1, n) returns the numbers from 1 to n as rows, so an INSERT ... SELECT over it writes n rows in one statement. teams goes first:
INSERT INTO teams (team_id, name)
SELECT i, 'Team-' || i
FROM generate_series(1, 3) AS i;
random() returns a number from 0 up to 1, and each call in a row draws a new one. players takes its team_id from the three ids that teams now holds, leaves position empty in about one row in ten, and picks one of four words for the rest:
SELECT setseed(0.5);

INSERT INTO players (player_id, team_id, name, position)
SELECT i,
       1 + floor(random() * 3)::int,
       'Player-' || i,
       CASE WHEN random() < 0.1 THEN NULL
            ELSE (ARRAY['goalkeeper', 'defender', 'midfielder', 'forward'])[1 + floor(random() * 4)::int]
       END
FROM generate_series(1, 1000) AS i;
setseed fixes the start of the random sequence for the session, so the same two statements give the same rows on the next run:
SELECT * FROM players ORDER BY player_id LIMIT 5;
| player_id | team_id | name | position |
|---|---|---|---|
| 1 | 3 | Player-1 | goalkeeper |
| 2 | 1 | Player-2 | forward |
| 3 | 1 | Player-3 | midfielder |
| 4 | 3 | Player-4 | forward |
| 5 | 2 | Player-5 | midfielder |
Counting the rows per position shows how the 1000 players spread:
SELECT position, count(*) FROM players GROUP BY position ORDER BY position;
| position | count |
|---|---|
| defender | 229 |
| forward | 239 |
| goalkeeper | 217 |
| midfielder | 222 |
| NULL | 93 |
1 + floor(random() * 3) works for team_id only because the team ids run from 1 to 3 without a gap. With ids that have gaps, the value has to come from the ids that teams holds, and every column that should look real, such as names, email addresses or dates in a range, needs an expression of its own.
Generate random data with DbSchema
The DbSchema Data Generator keeps one pattern per column and fills the tables in the order you set. Put both tables on a diagram first, because the generator works on the tables of the open diagram. Then choose Database → Data Generator, or press Data in the toolbar and choose Data Generator.

The dialog lists the tables of the diagram. For each one you set how many rows to generate in its Rows cell, and DbSchema shows whether the table is already empty or already holds data. The order of the list is the order the tables are filled, and it is the part worth checking before anything else: teams has to be populated before players, because every players.team_id has to match a team_id that already exists. Press Reorder, or move teams above players with the arrows.
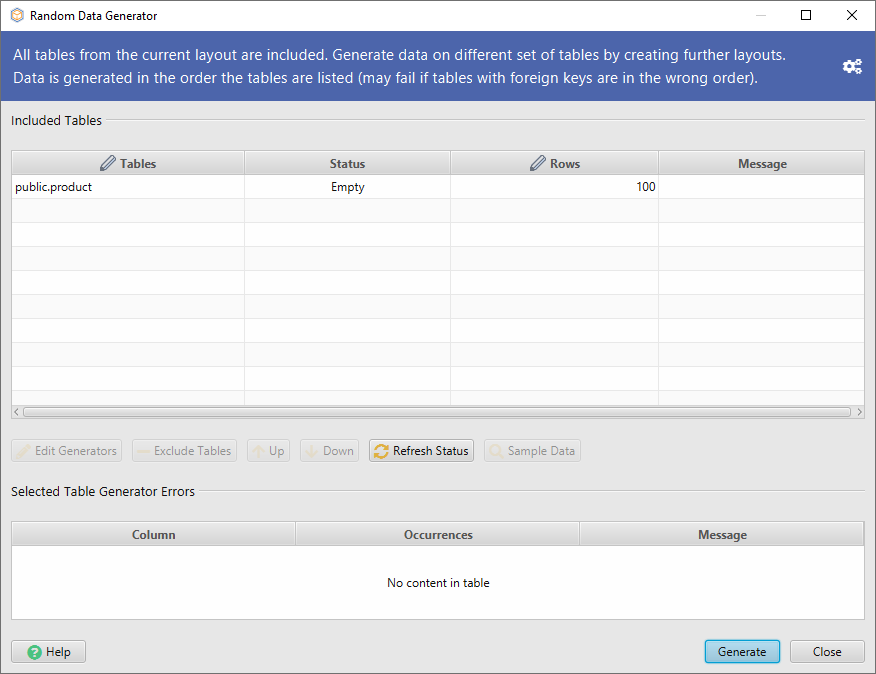
Clicking Generate writes the rows into the connected PostgreSQL database. Where a table already holds rows, DbSchema asks first whether to leave the current data or drop it, and on a production database the answer is Leave Current Data.
Choosing the pattern for each column
Select a table in the dialog and press Edit Generators. DbSchema has already guessed a pattern for every column from its name and its data type, and this is where you correct the guesses. Each column carries a pattern that produces the value, Null% as the percentage of rows left empty, and Seed, an integer that makes the values repeatable, so two columns given the same seed produce the same sequence.

A pattern that starts with a recognised keyword generates a value of that kind. sequence:from=1;step=1; counts up from 1 in steps of 1. int:from=0;to=100 picks a number between those two bounds. date:from='01.01.2020';to='01.01.2024'; picks a day inside that range. identity: marks the column as database-managed, so the generator skips it and PostgreSQL fills it.
Anything else is read as a reverse regular expression, which generates text matching the expression, so (goalkeeper|defender|midfielder|forward) on players.position puts one of those four words in every row. Literal text takes a repository pattern inline: Team-$Sequence on teams.name produces Team-1, Team-2 and so on.

Choose Generator opens the list of ready-made patterns, grouped by kind, with patterns for first names, last names, cities, email addresses and phone numbers. Pick one, adjust it if you want, and press Apply & Close.

The foreign key gets its own keyword. load_values_from_pk on players.team_id reads the primary key values already in teams and picks one at random for each row, which is why the table order matters. Every pattern you set is stored in the .dbs model file, together with the diagram, so the same generator configuration is there tomorrow and can be committed for the rest of the team.
Generating three rows in teams with sequence:from=1;step=1; and Team-$Sequence gives:
| team_id | name |
|---|---|
| 1 | Team-1 |
| 2 | Team-2 |
| 3 | Team-3 |
Look at the rows before you trust them
Generated data is worth having only if it looks like the real thing. The way to find out is to read some of it. Right-click teams on the DbSchema diagram and choose Data Explorer: the Data Explorer opens under the diagram on that table, where you can filter the rows without leaving the diagram.

Click a row, then the arrow button next to the table name, and open players from the foreign key. Selecting another team then reloads players with the players of that team, which is the check that matters after a generation run: if load_values_from_pk did its job, every team has players and no player points at a team that is not there. When a column is wrong, correct its pattern and generate again.
The Data Generator, and following foreign keys in the Data Explorer, are in the DbSchema Pro edition, and the Architect trial runs 15 days. Download DbSchema at https://dbschema.com/download.html, connect to your PostgreSQL database, drag the tables that need rows onto a diagram, and set the parent tables first in the list.










